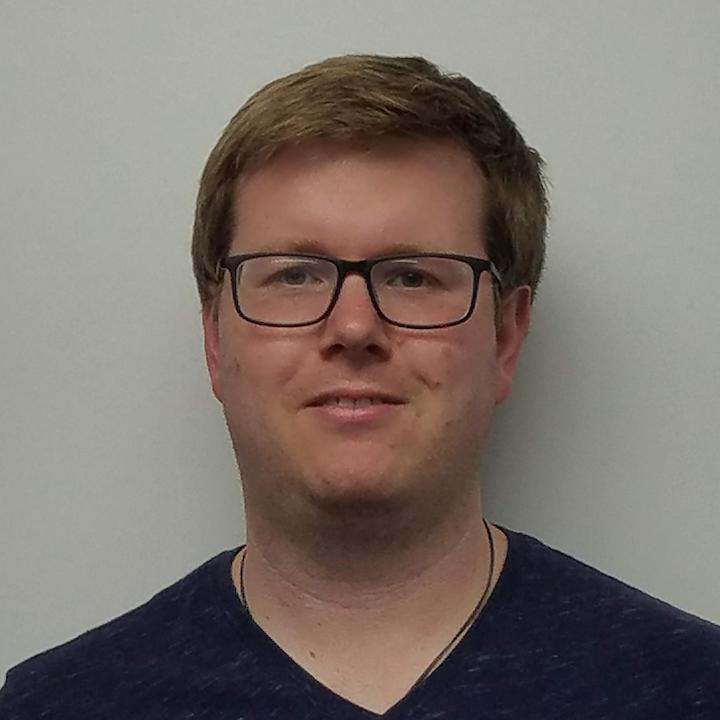
I lead Marin, an open lab for building foundation models, at Open Athena. Percy Liang and I started Marin at Stanford CRFM in 2024. We develop models in the open: code, data, experiments, training runs, failures, and results.
I also created Levanter, a JAX framework for large-scale model training. Before returning to research, I co-founded Semantic Machines, a conversational AI startup acquired by Microsoft. Earlier, I did my PhD at UC Berkeley and built Breeze, a numerical computing library for Scala that became part of the foundation of Apache Spark’s MLlib.
Selected work
Marin — An open lab for foundation model research. We train large models from scratch while publishing the code, data, experiments, and training process as we go.
Levanter — A legible, scalable JAX framework for training large language models and other foundation models on GPUs and TPUs. Levanter is now developed inside the Marin monorepo; the original repository still has useful historical documentation. Levanter is built on Haliax, the named-tensor library I designed for JAX, which makes large distributed models easier to read and modify.
Breeze — A numerical processing and linear algebra library for Scala. It later became the basis for much of Apache Spark MLlib's linear algebra.
Selected writing
There Is No Post-Training Data Commons
Why post-training needs a commons of tasks, not just documents, and what it would take to build one.
Open Athena · 2026
Thoughts on Marin's first year at Open Athena, chikungunya, and launching Marin's largest open training run yet.
Open Athena · 2026
Open Development of Frontier AI
Why the process of building frontier AI should be public, not just the models we release.
Open Athena · 2026
Introducing Marin: An Open Lab for Building Foundation Models
What Marin is, why we built it, and how the open-lab model works. Things have gotten messier in the age of agents, but the commitment stands.
Stanford CRFM · 2025
A roller-coaster marathon of hardware changes, loss spikes, and mid-run interventions.
Stanford CRFM · 2025
Lessons from our first serious attempt to train a competitive open model from scratch.
Stanford CRFM · 2025
A few papers
I don't write many papers these days. These are some favorites.
Studying the History of Ideas Using Topic Models
Hall, Jurafsky, Manning · EMNLP · 2008
Sparser, Better, Faster GPU Parsing
Hall, Berg-Kirkpatrick, Klein · ACL · 2014
Hall, Durrett, Klein · ACL · 2014
Ancestry-Constrained Phylogenetic Analysis Supports the Indo-European Steppe Hypothesis
Chang, Cathcart, Hall, Garrett · Language · 2015
Task-Oriented Dialogue as Dataflow Synthesis
Andreas et al. · TACL · 2020
Fantastic Pretraining Optimizers and Where to Find Them
Wen, Hall, Ma, Liang · arXiv · 2025
Earlier
I co-founded Semantic Machines in 2014. We built a conversational AI system around a dataflow/program-synthesis representation of dialogue; Microsoft acquired the company in 2018, and parts of the technology later shipped in Outlook.
Before that I was in Dan Klein’s group at UC Berkeley, working on natural language processing and computational historical linguistics. Somewhere along the way I also helped build a StarCraft AI that won the first AIIDE StarCraft AI competition.
Elsewhere
GitHub · Google Scholar · X · LinkedIn · Open Athena · Marin · Stanford CRFM
Email: david dot hall at openathena dot ai